LLM & Generative AI Adoption Consulting
Technical advisory from use-case design and PoC to building in-house capability
You want to adopt LLMs, but nobody in-house can decide between a commercial API and a local LLM, how to build RAG, or whether fine-tuning is worth it, while vendor proposals keep piling up. That is the moment to talk to us.
We operate our own GPU cluster and train and serve LLMs every day. As technical advisors we assemble the material your decision needs: technology research, architecture reviews, vendor proposal evaluations, and explanatory material for executives. We do not take over the whole build; we raise the quality of your decisions.
LLM/Generative AI
Technical Selection & Architecture Design Advisory
Expert advice on optimal technology selection and adoption strategy.
Commercial API vs open-source LLM, RAG architecture decisions, fine-tuning feasibility— we support your technical decision-making for LLM adoption. We provide materials for informed decisions: technical research reports, architecture reviews, and vendor proposal evaluations.
Advisory Areas
Commercial API vs Local LLM
- Cost comparison & estimation
- Security requirements analysis
- Latency & throughput evaluation
- Use-case specific recommendations
Open Source LLM Selection
- Llama/Mistral/Qwen comparison
- Performance evaluation
- License & usage terms analysis
- Model size vs performance tradeoffs
Fine-tuning Strategy
- LoRA/QLoRA applicability assessment
- Continued pre-training vs fine-tuning
- Data requirements & cost estimation
- Effectiveness measurement advice
RAG Design Review
- Architecture design review
- Vector DB selection advice
- Accuracy improvement proposals
- Vendor proposal technical evaluation
Consultations We Handle
- Considering LLM adoption but lack technical decision-making expertise
- Need third-party evaluation of vendor proposals
- Want to compare costs and benefits of commercial API vs local LLM
- Need to estimate fine-tuning effectiveness and costs upfront
- Need technical briefing materials for executive presentations
- Want GPU configuration and cost estimates for LLM training/inference
Our Expertise
Operating our own GPU clusters and conducting LLM training and inference daily, we can share the following specialized knowledge:
LLM Training Realities
We explain the differences between full-scratch training, continued pre-training, and fine-tuning, along with realistic estimates for GPU requirements, timeframes, and costs.
Understanding Scaling Laws
We cover optimal balance between model size and data volume based on Chinchilla scaling laws, MoE (Mixture of Experts) architecture mechanics, and latest technical trends.
GPU Selection & Cost Estimation
We provide practical information on A100/H100/L40S characteristics comparison, NVLink importance, and cloud GPU vs on-premise TCO analysis.
Value We Provide
Vendor-Neutral Evaluation
From a position independent of any specific vendor, we advise on optimal technology selection for your needs.
Operations-Based Expertise
From our experience operating LLM products on our own GPU clusters, we provide practical advice, not just theory.
Documentation & Meeting Support
We directly support decision-making through technical research reports, comparison documents, and participation in technical review meetings.
Related Resources
We publish technical articles about LLM/Generative AI on the Qualiteg Blog.
Is GPT-6 Astra AGI? How It Differs from Claude Fable 5.1, Pricing, and What It Means for Your Work
What makes GPT-6 Astra stand out? We compare performance and pricing with Claude Fable 5.1, plus the ChatGPT Pro and Claude Max 20x plans, and share the AGI-like progress and what we noticed in real development, with diagrams.

Use Your Home PC's Local LLM from Your Smartphone — Ollama + Open WebUI + WireCanal
A measured, step-by-step guide to putting a chat UI (Open WebUI) on your home PC's local LLM (Ollama + gemma4) and using it securely from your smartphone through a tunnel. No Docker, no WSL, no port forwarding.

How to Build an MCP Server — Connecting Your Custom MCP Server to Web-Based ChatGPT and Claude (Part 2)
A hands-on guide to connecting your custom MCP server to web-based ChatGPT and Claude, with actual connection screenshots. Add a public URL and OAuth to your localhost server and query your sales database in natural language — without changing a single line of code.

How to Build an MCP Server — Making a Database Answer AI Questions in Japanese with Python and FastMCP (Part 1)
A hands-on guide to building your own MCP server with Python and FastMCP, letting AI answer questions about a SQLite sales database in natural language — with working code from start to finish.

Kimi K3 In-Depth Research — 2.8 Trillion Parameters: Can the "Largest-Ever Open Weights" Deliver?
A comprehensive pre-release analysis of Moonshot AI's 2.8-trillion-parameter Kimi K3 — from architecture to implementation challenges, based on public information and independent evaluations.

What's Next for Claude Fable 5? A Fact-Based Look at Its Background, Costs, and Outlook
From suspension and revival to leaving the subscription tier — the confirmed pricing and cost outlook, with facts separated from speculation.

When Will a Mythos-Level Open Model Arrive?
Estimating when open models will catch up with the gated frontier, using historical open-source lag data.

API Pricing Tables for Major LLM Providers — Claude / GPT / Gemini / Grok (as of May 13, 2026)
Side-by-side per-1M-token pricing across major providers — a baseline for model selection and cost design.

Anthropic Released a Model 'Too Powerful to Release' — Mythos
What the invite-only frontier model and Project Glasswing signal: a paradigm shift toward the defender's advantage.

Japanese LLM Ranking 2026 — Benchmark Analysis Report (March 6 Edition)
A comprehensive analysis of Japanese-capable LLMs based on Nejumi Leaderboard 4 — the landscape shifted again in just three months.

Vertical Integration by AI Platformers and the Remaining Strategic Options
How AI platformers are moving into the SaaS layer, and where viable strategic positions remain.
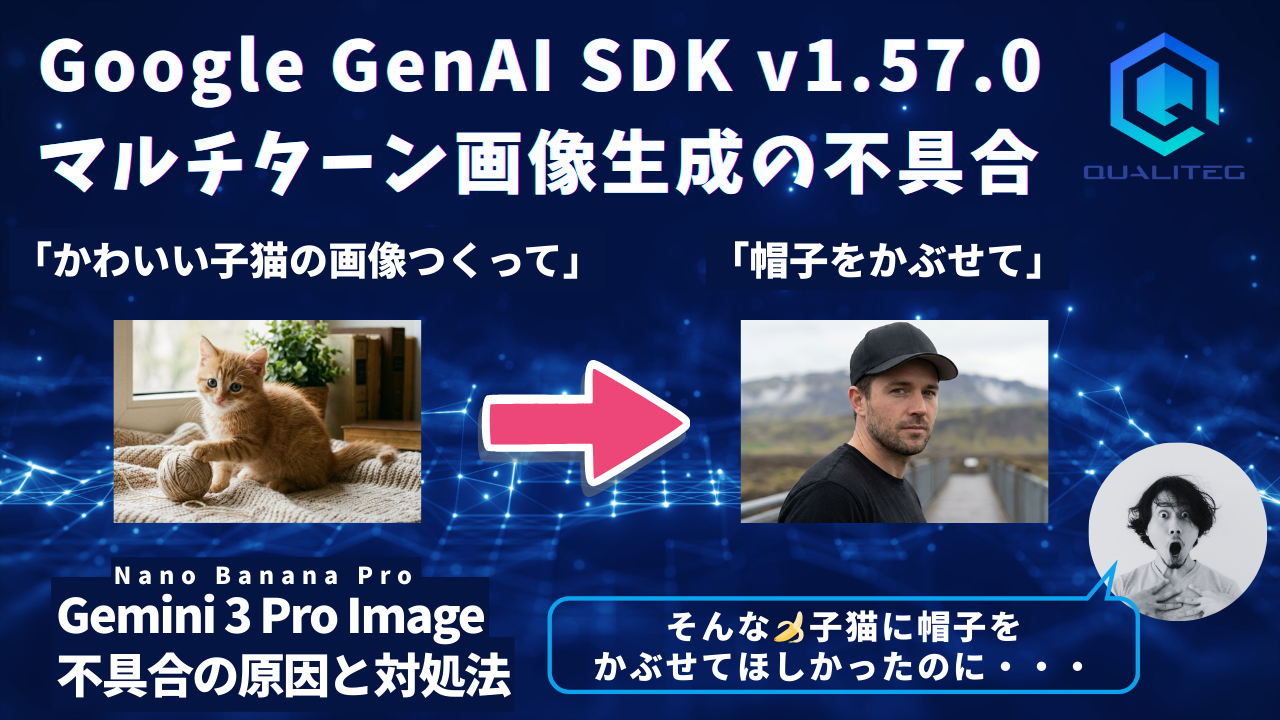
Google GenAI SDK マルチターン画像編集の問題と対処法
Sharing the issue and solution for unstable multi-turn image editing with Gemini 3 Pro Image streaming.
LLM学習の現実:GPU選びから学習コストまで徹底解説
Explaining the reality of LLM training with specific numbers on GPU requirements, duration, and costs.
Model Context Protocol完全実装ガイド 2025
Complete guide from MCP specification evolution to latest Streamable HTTP with full source code.
日本語対応 LLMランキング2025 ~ベンチマーク分析レポート~
Comprehensive analysis of Japanese LLMs based on Nejumi Leaderboard 4 benchmark data.
【解説】Tekken トークナイザーとは何か?
Explaining Mistral's new-generation Tekken tokenizer and its differences from traditional tokenizers.
日本語対応!Mistral Small v3 解説
Explaining the Japanese-capable small model that achieves 70B+ performance with only 24B parameters.
「Open Deep Research」技術解説
Deep dive into HuggingFace's Open Deep Research architecture and implementation.

Meta社が発表した最新の大規模言語モデル、Llama 3.1シリーズの紹介
Introducing the Llama 3.1 series available in 8B, 70B, and 405B sizes.
Mistral AI社の最新LLM「Mistral NeMo 12B」を徹底解説
Explaining the Apache2-licensed 12B parameter model's features and performance.
革新的なコード生成LLM "Codestral Mamba 7B" を試してみた
Hands-on report with the new code generation LLM using Mamba architecture.
ChatStream🄬でLlama-3-Elyza-JP-8B を動かす
Testing the Japanese LLM "Llama-3-Elyza-JP" 8B version said to outperform GPT-4.
Frequently Asked Questions
We cannot decide between a commercial API and a local LLM. What are the criteria?
We compare four points: cost, security requirements, latency and throughput, and the use case. Workloads that cannot send confidential data outside usually go local, and early experiments usually start with a commercial API. We estimate the GPU configuration and cost first, then decide together which fits your conditions.
Which open-source LLM should we choose? We are concerned about Japanese performance.
We compare candidates such as Llama, Mistral and Qwen on Japanese performance, license and terms of use, and the trade-off between model size and capability. We also explain how to read benchmarks, in the same way as the Japanese LLM ranking we publish on our blog.
Do we really need fine-tuning? We would like a cost estimate as well.
We first check whether RAG and prompt design are enough. If not, we assess whether LoRA/QLoRA applies, how it differs from continued pre-training, and estimate the data volume, number of GPUs, duration and cost. We also agree on how to measure the effect before starting.
What form does the engagement take? Can we also outsource development?
We work as technical advisors. We provide decision material through technology research reports, architecture design reviews, vendor selection support, technical documentation and participation in meetings. A free initial consultation of about one hour is available.
CONTACT
Contact Us
For questions or consultations about AI Technology Consulting,
please feel free to contact us.